Factor IO · Bangkok engineering studio
The platform comes first. Everything else runs on it.
Kubernetes platforms, the infrastructure underneath them and the private AI on top, built by the architect who scopes the work.
The studio Where Factor IO comes from, and why it builds the running system rather than the slide.
What the film shows
Where we come from. Nearly 20 years inside enterprise infrastructure. Ecosystem Solutions Architect for Red Hat and Nutanix, working alongside Thailand's systems integrators.
The gap. Most projects stall between the slide and the running system. The design is sound. The platform underneath it is where the work gets hard.
What we build. So we build the running system, from bare metal up. Hardware, Kubernetes, data and controls, delivered as one piece of work.
The studio. One principal-led studio. Platform first, AI on top. Bangkok, Thailand
Every serious AI project becomes a platform project.
A model is easy to demo. Running one for a business takes GPU scheduling, data kept on premises, identity, an audit trail and a way back after failure. That is a platform, and once it exists it carries your applications, databases and pipelines as well. We build it once, properly, and AI is the workload we know best.
The platform thesis Why every serious AI project turns into a platform project, and why that platform should carry more than AI.
What the film shows
The model. The model is the easy part. A demo needs a model and a laptop. Production needs everything around it.
What it needs. Then it needs GPUs, data, identity, audit and recovery. Scheduling, data kept on premises, access control, an audit trail and a way back after failure.
A platform. That is a platform. It carries more than AI. Applications, databases and pipelines run on the same foundation.
Build once. Build the platform once. Run whatever comes next. Kubernetes first. AI is the specialisation.
Four services, one platform underneath.
Each can be an engagement of its own or one stage of the same delivery. The platform comes first because everything else sits on it.
What we deliver Four services on one platform, from the cluster to the decision a person still has to make.
What the film shows
Kubernetes and GPU platform. Clusters that schedule GPUs and survive a failed node. OpenShift, Nutanix NKP or upstream Kubernetes, on bare metal or air-gapped.
Private AI. Models served inside your network. Nothing leaves. Open-weight models on vLLM or Triton, sized to the GPUs you own.
Knowledge and authority. The right source, for the right people. Which documents are authoritative, and who may read them, is settled before anything is indexed.
AI governance. An agent can ask. A person decides. Anything outside the agreed scope stops until someone accountable approves it.
Scoped, built and handed over to your team.
OpenShift, Nutanix NKP or upstream Kubernetes, on bare metal or air-gapped. Capacity, recovery, upgrades and day-to-day ownership are designed in.
Open-weight models served inside your network on vLLM or Triton, sized to the GPUs you own. Your data stays put, and there is no per-token bill.
Which documents are authoritative, who may read them and how they stay current, settled before anything is indexed.
What an agent may do on its own, and what waits for a person. Enforced by the execution layer, not requested in a prompt.
What we have for sale: four commercial packages.
Concrete systems and architectural deliverables you can buy standalone or as a full build, scoped directly with the principal engineer and quoted within 48 hours.
01 · Enterprise Kubernetes and GPU platform build
Deliverable: production Red Hat OpenShift, Nutanix NKP or CNCF Kubernetes cluster on bare metal or air-gapped, with NVIDIA GPU scheduling, recovery drills and Day-2 runbooks. Typical timeline: 2 to 6 weeks.
02 · Turnkey Private AI and Thai operations system
Deliverable: customer-data fine-tuned Thai LLM (OpenThaiGPT, SeaLLMs v3, Qwen2.5-Thai), LINE OA intake, ภ.พ.20 and PromptPay slip verification, operator console and SAP, Express or FlowAccount connectors. Timeline: 2 to 4 week pilot.
03 · Enterprise knowledge and document authority system
Deliverable: source-of-truth authority matrix, department RBAC permissions, PostgreSQL pgvector ingestion pipeline, PDPA deletion hygiene and citation-enforced internal Q&A. Typical timeline: 2 to 4 weeks.
04 · Principal architect assessment and SI deal support
Deliverable: vendor-neutral hardware and GPU BOM sizing, 36-month TCO comparison, mechanical AI governance blueprint, or joint presales and PoC execution for SI partners. Timeline: 1 to 2 week fixed sprint.
See full commercial catalog and how to buy Try the live Private AI workbench
Work directly with the architect doing the work.
Thanat Manasakool, Founder and Principal Engineer. Nearly 20 years in enterprise infrastructure, including time as an Ecosystem Solutions Architect for Red Hat and Nutanix, advising Thailand's leading systems integrators. The person who scopes your project is the person who builds it.
Two ways in. A quotation within 48 hours.
Every environment has its own hardware, security constraints and data policies, so there is no price list. We scope the work with you and send an itemised quotation within 48 hours.
For your business
An architecture review, a private AI pilot or a full production delivery, scoped directly with the principal engineer.
Who holds the customer relationship You hold the direct relationship, and we are accountable for the agreed delivery.
For technology partners
Principal-level architecture for your client opportunities, from discovery and sizing to proof of concept and implementation. We work with vendors, distributors and systems integrators.
Who holds the customer relationship Your team holds the client relationship, and we take responsibility for the technical delivery.
Built in the studio
Tools and apps we make for ourselves, to the same standard as client work.
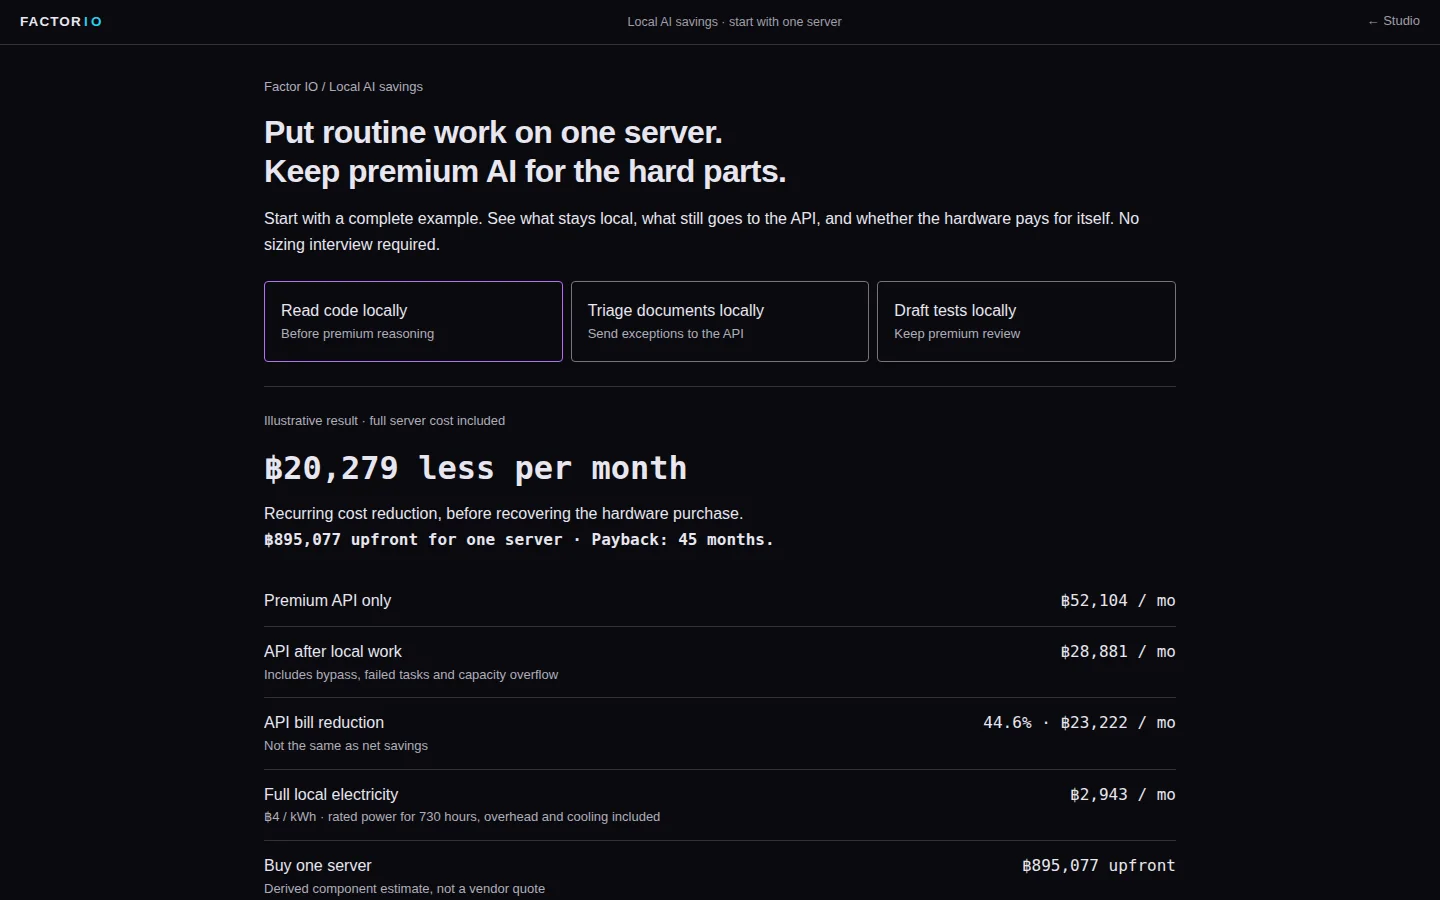
Local AI cost calculator
What stays local, what still goes to an API, and whether the hardware pays for itself.
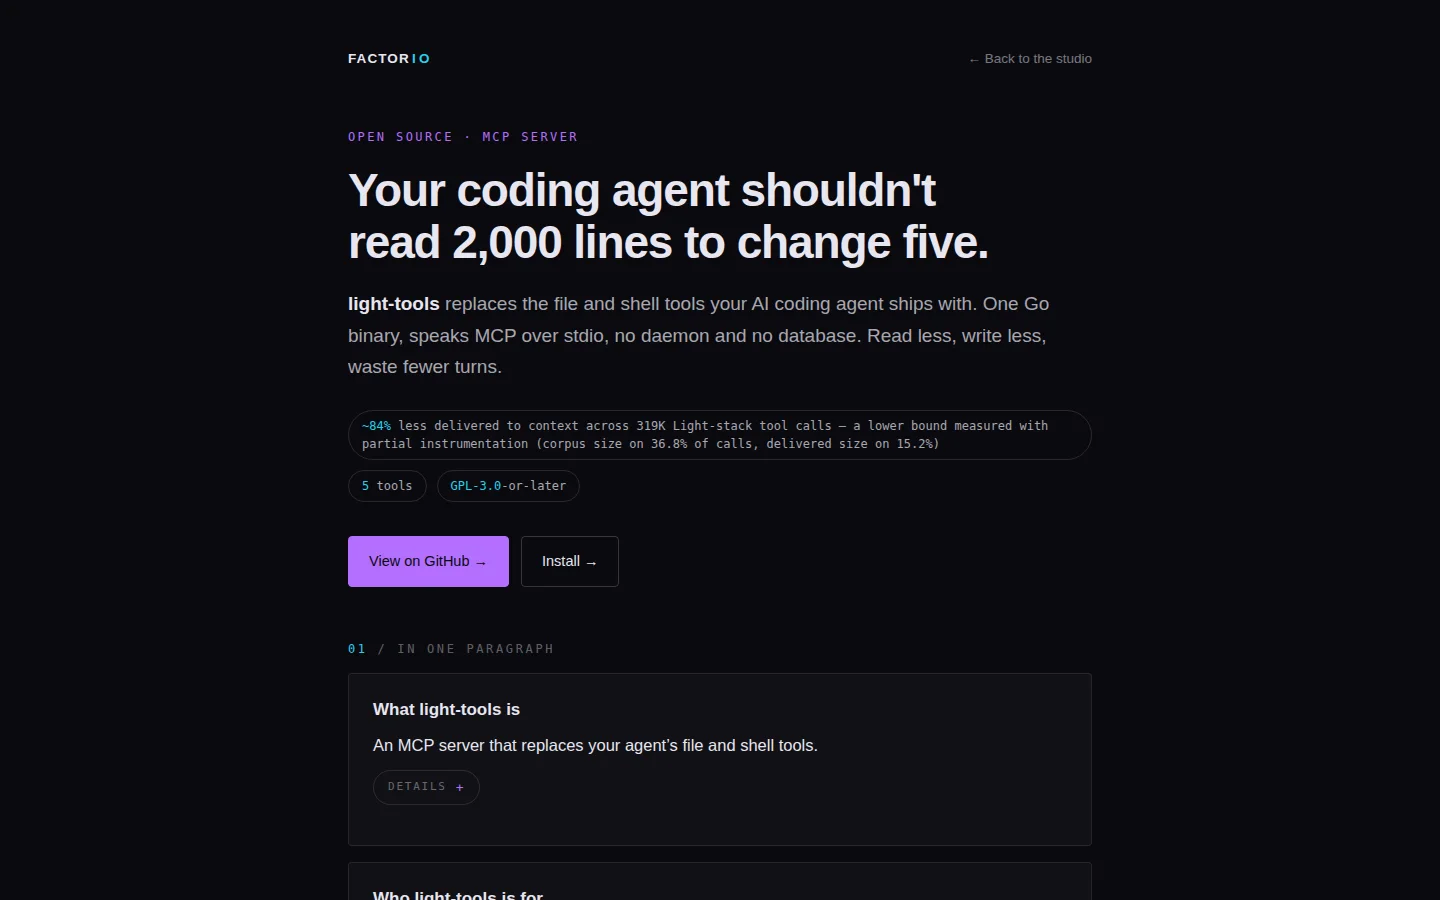
light-tools
An MCP server that replaces a coding agent's file and shell tools. One Go binary.
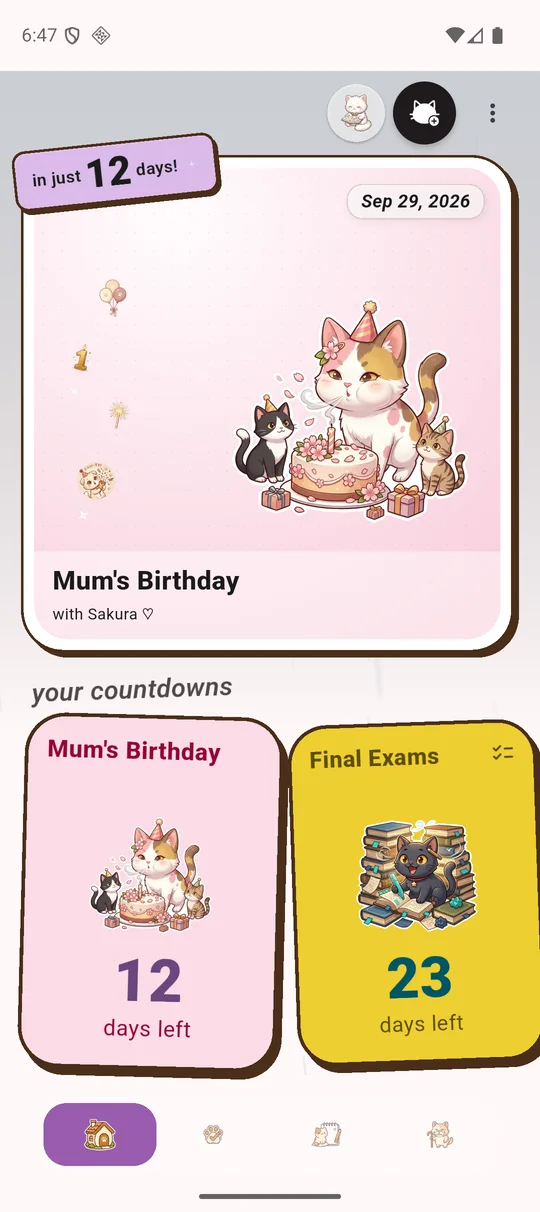
Cat Countdown
A cosy life organiser with nine cats: countdowns, tasks, sticker notes and alarms.
Blink
A privacy app that runs entirely on the device. No data collection, no accounts, no analytics.
Talk to the architect who will build it.
Tell us what you want to achieve and what you run today. We scope the work and send an itemised quotation within 48 hours.